Introduction
This blog reflects my journey through Machine Learning, Reinforcement Learning, and Robotics. While my current work spans these areas, my academic roots are in Statistics, a foundation that continues to shape how I think about problems. From a theoretical standpoint, I believe Statistics remains the core foundation of modern machine learning.
Over time, while studying statistics, I often encountered concepts that felt confusing, subtle, or easy to misunderstand. Some of them became clearer after revisiting the ideas multiple times or thinking about them from different perspectives, while others are still things I occasionally find myself reflecting on.
In this series of notes, I plan to write down those questions, confusions, and small clarifications, both as a personal record and as a way to organize my own understanding of statistical concepts.
Uncategorized (yet)
What exactly is the random variable?
First, I want to clarify this since notations related to it are sometimes confusing. Random variable is a function from a sample space to the real numbers. It is a function that maps each outcome of a random experiment to a real number. $$ X : \Omega \rightarrow \mathbb{R} $$
Although it is called a variable, it is important to remember that a random variable is actually a function, not a variable in the usual sense.
For example, if we flip two coins, the sample space is {HH, HT, TH, TT}. And the random variable X is the number of heads. $$ X(HH) = 2, X(HT) = 1, X(TH) = 1, X(TT) = 0 $$ $$ X : \{HH, HT, TH, TT\} \rightarrow \{0, 1, 2\} $$ So, random variable is a function, not a variable.
$$ P(X=x) $$ At first glance, this can be confusing. What exactly is $x$? Is $x$ an input of the function $X$? No. The input of $X$ is an outcome of the random experiment. So, $x$ is the output of the function $X$. More precisely, $$ P(X=x) = P(\{ \omega \in \Omega | X(\omega) = x \}) $$ For example, $P(X=1) = P(\{ \omega \in \Omega | X(\omega) = 1 \}) = P(\{ HT, TH \}) = 1/2$.
Intuitively, Why Does Integrating $-F(x)$ and $1-F(x)$ Give $E(X)$?
Typically, the definition of expected value is given as: $$ E(X) = \int_{-\infty}^{\infty} x f(x) dx \tag{1} $$ But there’s another way to get $E(X)$ using the cumulative distribution function $F(x)$. $$ E(X) = -\int_{-\infty}^{0} F(x) dx + \int_{0}^{\infty} (1-F(x)) dx \tag{2} $$ Intuitively, (1) is quite straightforward. It is the weighted average of all possible values of $X$ by their probabilities. If you think it in visual way, it is like this:
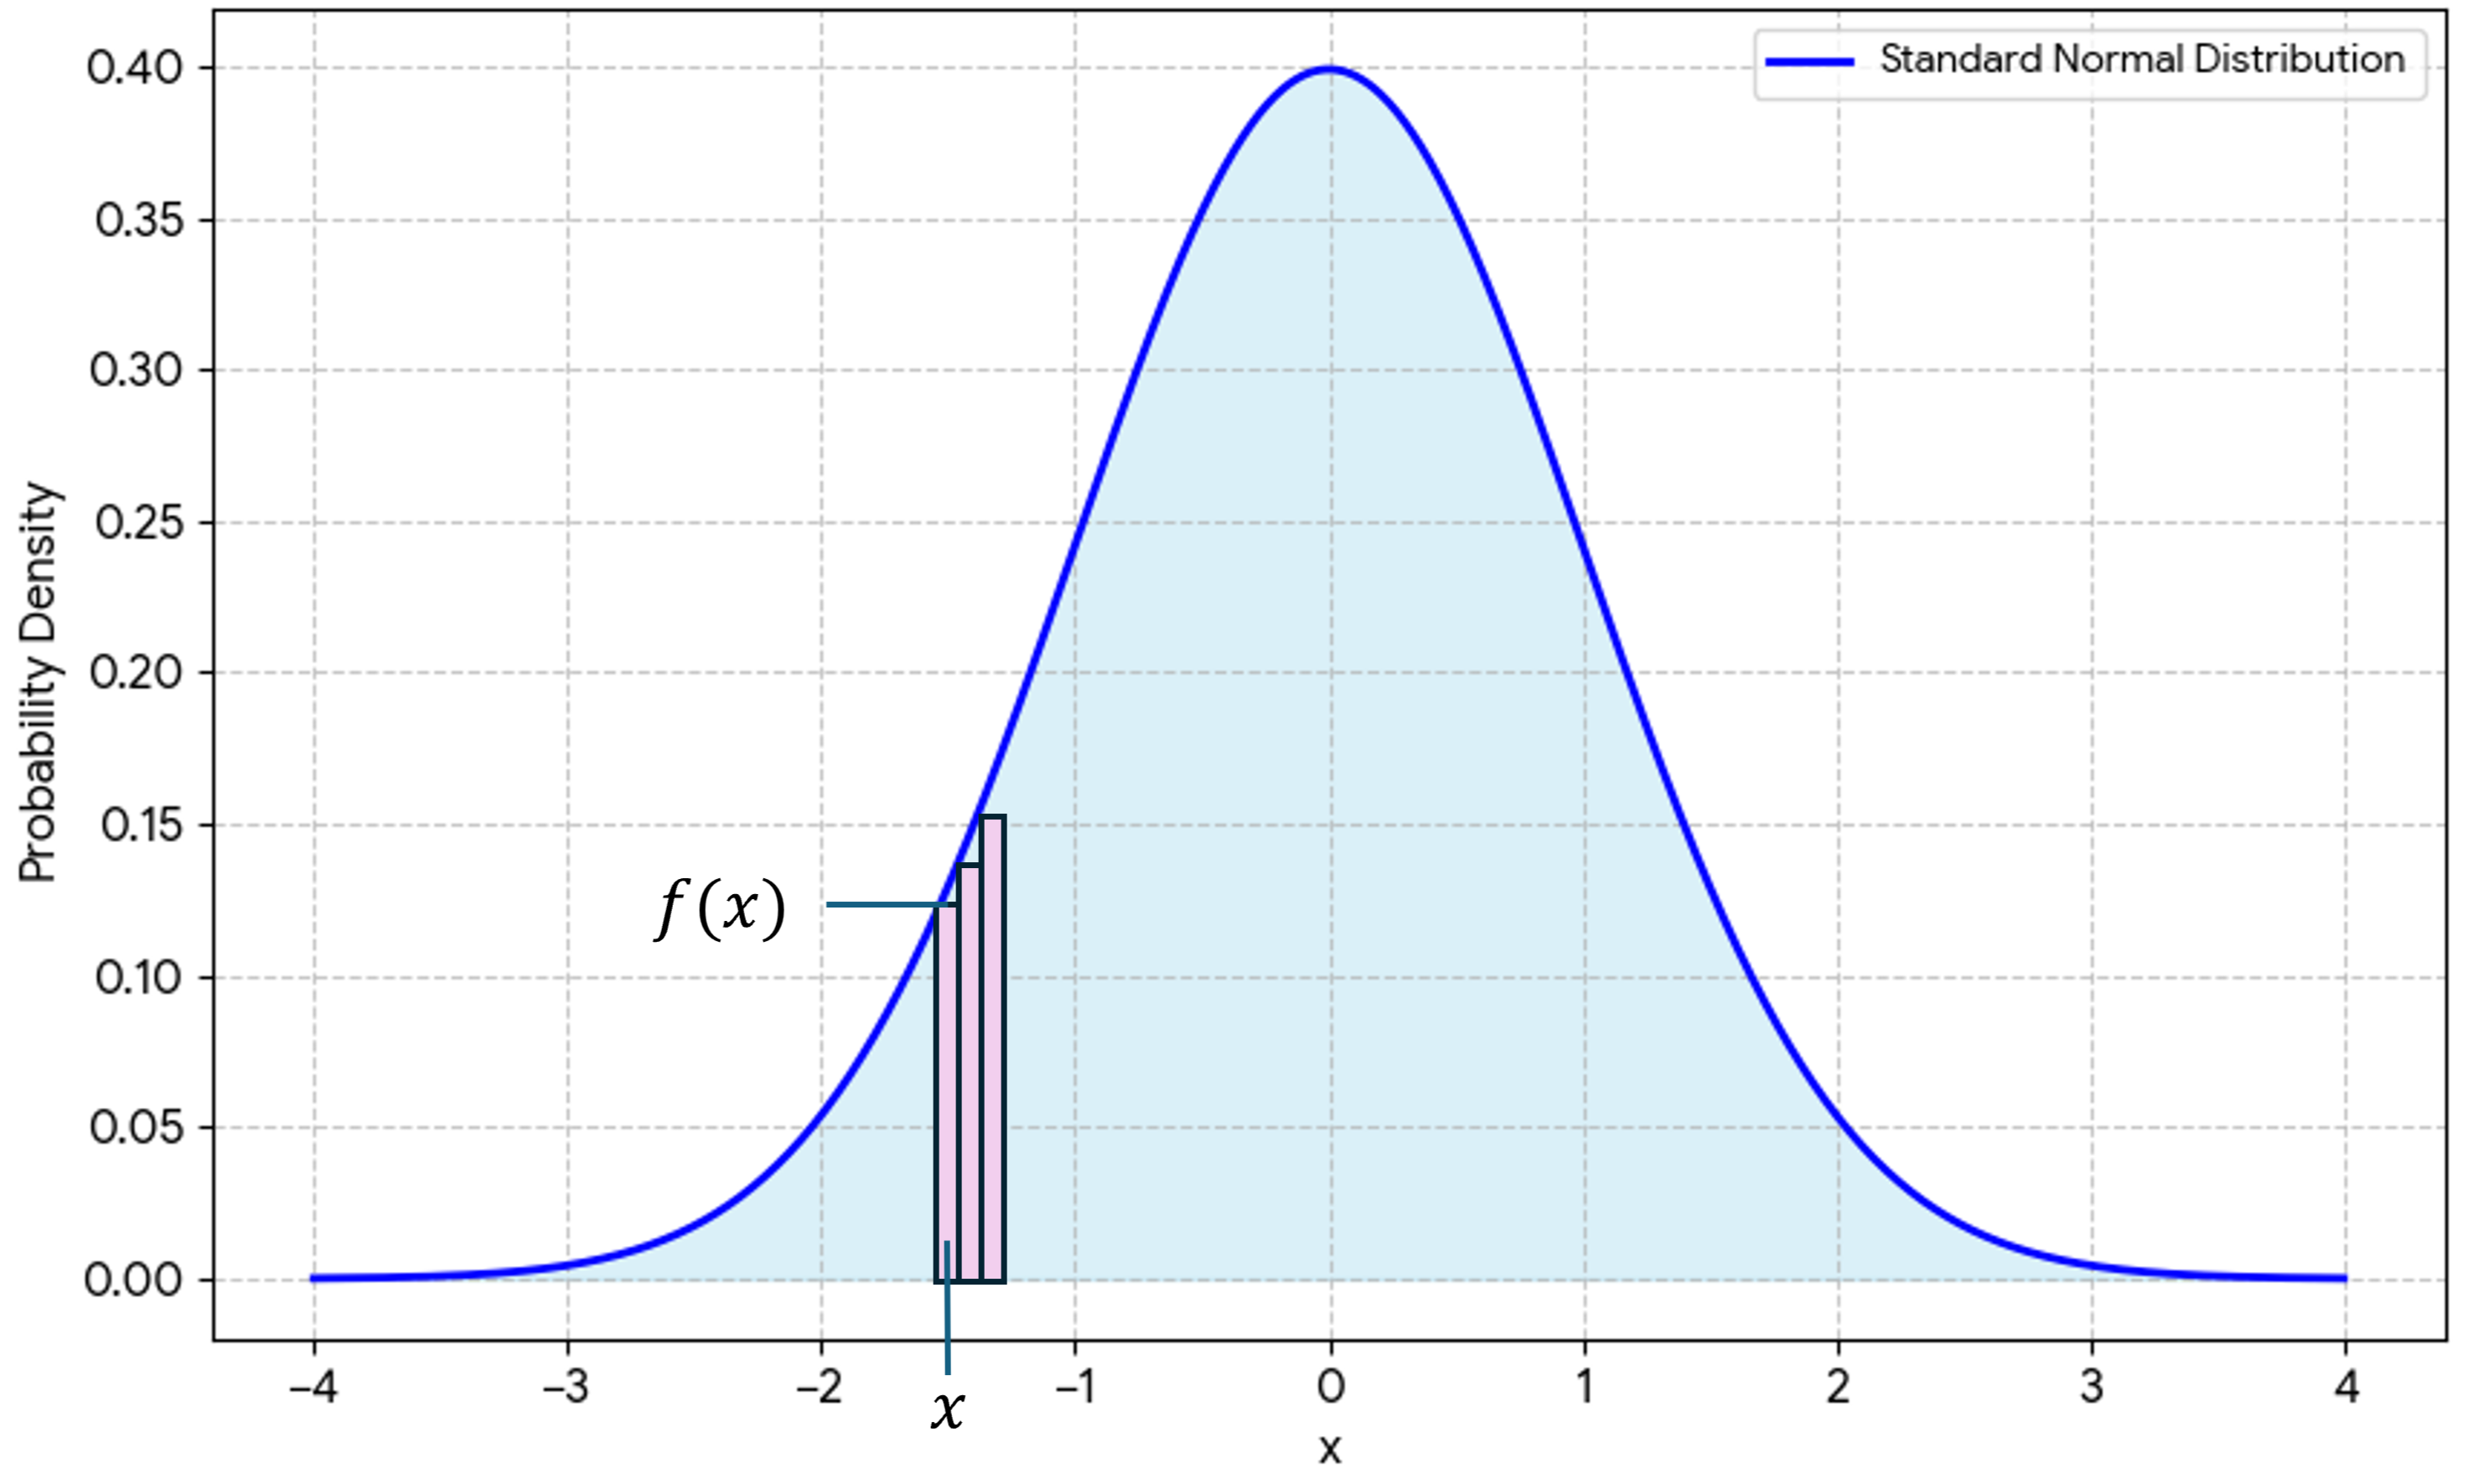
-1.5 * 0.12 + -1.4 * 0.13 + … Intuitively, this sure be $E(X)$.
Whay about (2)? It is like this:
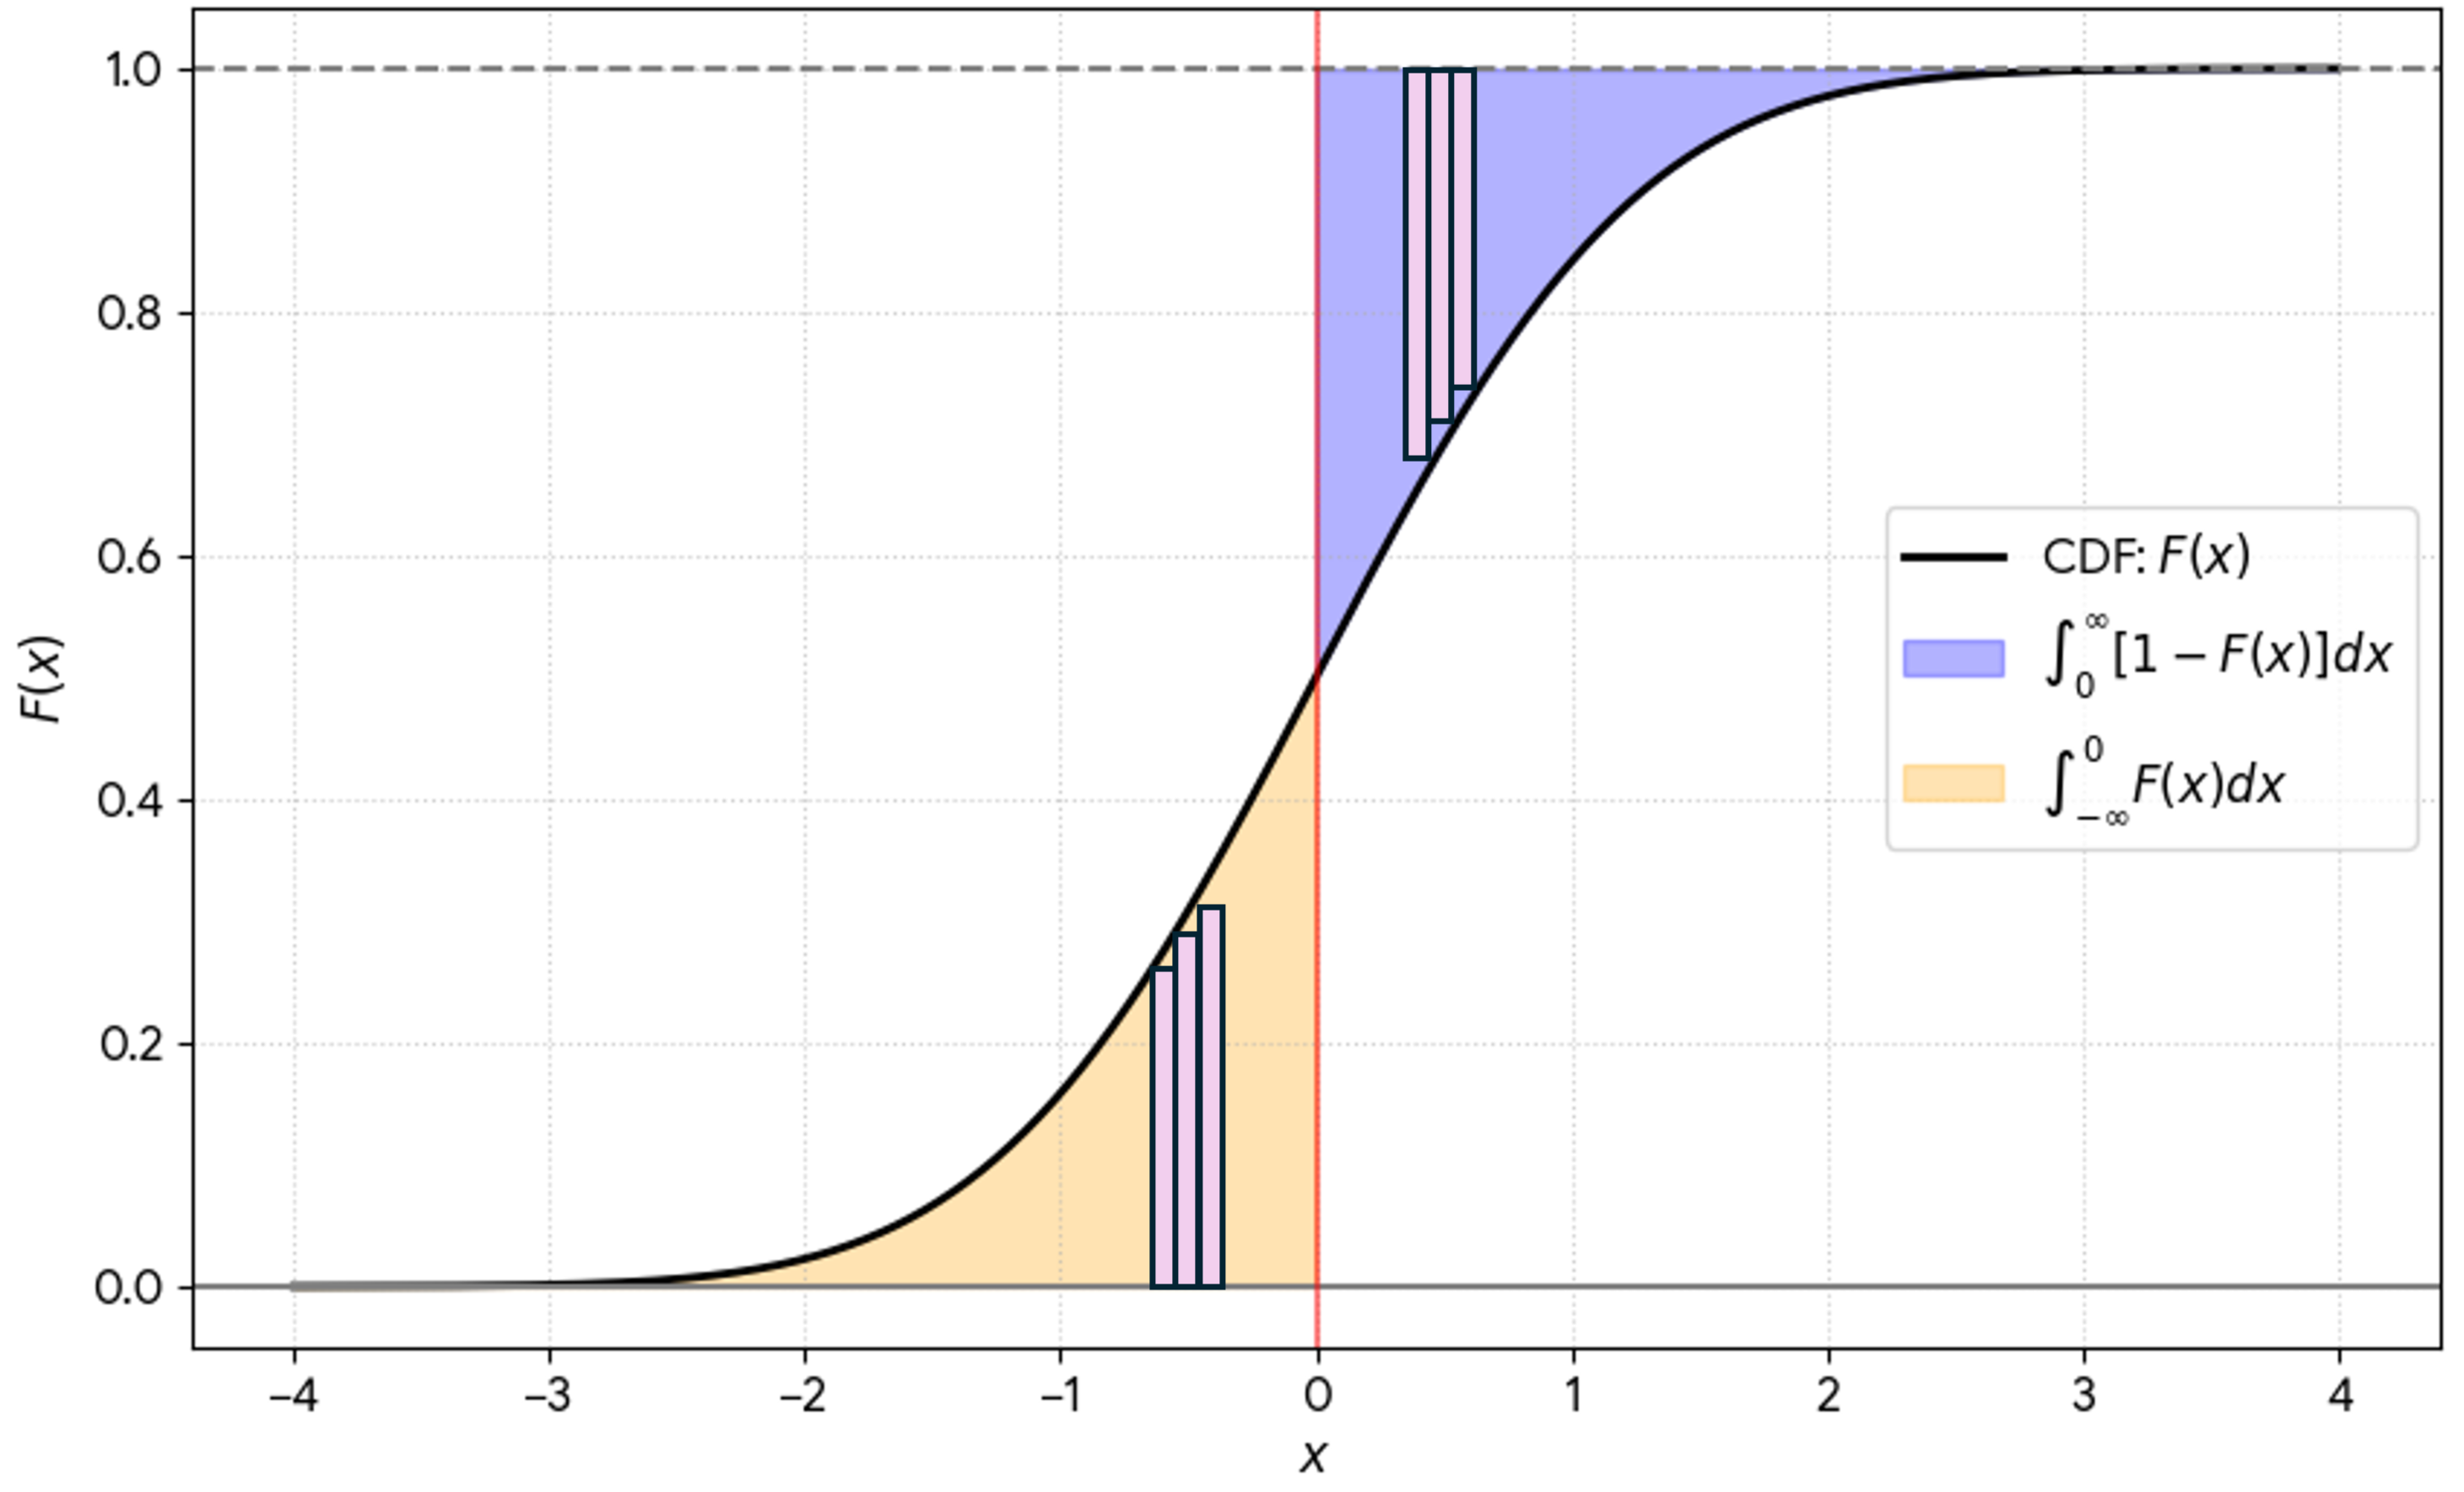
In the positive side ($\int_{0}^{\infty} 1-F(x) dx$), imagine a crowd moving forward. At each step $dx$, the height $1-F(x)$ represents the proportion of people who have traveled at least distance $x$. Summing these vertical slices (height $\times$ width) naturally gives us the average distance traveled (if the $y$-axis were measured in kilometers instead of proportions, this integral would simply represent the total distance traveled by all people moving in the positive direction).
On the negative side ($\int_{-\infty}^{0} F(x) dx$), the height $F(x)$ represents those who moved backward beyond point $x$. Since the integration of a positive height over a width always yields a positive area, we manually apply a negative sign to account for the direction. Summing these two parts gives us the true center of mass: $E(X)$.
Then What about $E(X^2)$?

Think of the figure above as representing people running. Because the y-axis represents the number of people, the total shaded area does not represent $E(X)$, but rather the total distance run by all people.
Suppose that after the race is over, we want to know the total distance everyone ran. One way to compute this is the following. We shout to the runners: “Raise your hand if you ran more than 1 meter!”, “More than 2 meters!”, “More than 3 meters!”, …, “More than 150 meters!”, …, “More than 200 meters!”. Each time we count how many people raise their hands. If we add up all these counts, we obtain the total distance run by everyone.
To see why this works, consider a particular runner who ran 150 meters. He will raise his hand for every question from 1 meter up to 150 meters. Therefore he will be counted 150 times: $$ 1 + 1 + … + 1 = 150 $$ So each runner contributes exactly his running distance.
Now suppose we want to compute something different: the sum of squared distances. For the same runner who ran 150 meters, how could we obtain $150^2$ using a similar counting idea? Consider summing even numbers from 2 to 300: $$ 2(1+2+3+…+150).$$ $$ 2* \frac{150(150+1)}{2} = 150*151 $$ This is slightly larger than $150^2$. The discrepancy comes from the fact that we were counting in discrete steps (1 meter, 2meters, 3meters, …). When we move to a continuous perspective, these small step errors disappear. In the continuous case, the square can be represented exactly as $$x^2 = 2 \int_{0}^{x} t dt$$ This leads to the identify $$ E(X^2) = 2 \int_{0}^{\infty} x(1-F(x)) dx $$ As generalization, we can get the following identity: $$ E(X^2) = 2 \int_{0}^{\infty} xP(|X| > x) dx $$ $$ E(X^2) = 2 \int_{0}^{\infty} x(1-F(x) + F(-x)) dx $$